# What the tf-sampler-i547 branch of greta runs, in a fresh R session: run.R
# sources it once per session, and keeps the list it ends with. Each
# `# ---- label ----` line starts a section that index.qmd shows by that label.
#
# It reaches into greta's internals, so it needs the branch:
#
#   Rscript --quiet --vanilla posts/2026-10-07-tfp-alternatives-i547/benchmark.R

# ---- benchmark-setup ----
library(greta)
library(bench)
session <- as.integer(Sys.getenv("GRETA_BENCH_SESSION", "1"))
session_seed <- 2026 - 10 - 7 + session
tfp <- reticulate::import("tensorflow_probability")
tf <- tensorflow::tf
builtins <- reticulate::import_builtins()

# ---- benchmark-settings ----
# sampling_iterations is the length of each timed sampling call;
# opt_max_iterations are the iteration limits opt() is timed at, with a
# tolerance of 0 so it runs all of them; the *_calls settings count timed calls
bench_settings <- list(
  chains = 4,
  warmup = 1000,
  sampling_iterations = 2000L,
  sampling_calls = 6,
  opt_max_iterations = c(100L, 1000L),
  opt_learning_rate = 0.1,
  opt_calls = 6
)

# ---- model-linear ----
build_linear <- function() {
  int <- normal(0, 10)
  coef <- normal(0, 10)
  sd <- cauchy(0, 3, truncation = c(0, Inf))
  mu <- int + coef * attitude$complaints
  distribution(attitude$rating) <- normal(mu, sd)
  model(int, coef, sd)
}

# ---- model-hierarchical-linear ----
build_hierarchical_linear <- function() {
  int <- normal(0, 10)
  coef <- normal(0, 10)
  sd <- cauchy(0, 3, truncation = c(0, Inf))
  species_sd <- lognormal(0, 1)
  species_offset <- normal(0, species_sd, dim = 2)
  species_effect <- rbind(0, species_offset)
  species_id <- as.numeric(iris$Species)
  mu <- int + coef * iris$Sepal.Width + species_effect[species_id]
  distribution(iris$Sepal.Length) <- normal(mu, sd)
  model(int, coef, sd, species_sd, species_offset)
}

# ---- tfp-leapfrog-kernel ----
# hmc() as a TFP kernel. TFP's HamiltonianMonteCarlo takes one leapfrog count
# when it is built, and reads it from its kernel results instead when built
# with store_parameters_in_results = TRUE; this wrapper writes a fresh count,
# between Lmin and Lmax, into those results every step. MetropolisHastings
# passes accepted_results to the uncalibrated kernel, so the count goes there.
RandomLeapfrog <- reticulate::PyClass(
  "RandomLeapfrog",
  inherit = tfp$mcmc$TransitionKernel,
  defs = list(
    `__init__` = function(self, inner_kernel, l_min, l_max) {
      self$inner_kernel <- inner_kernel
      self$l_min <- l_min
      self$l_max <- l_max
      NULL
    },
    is_calibrated = builtins$property(function(self) TRUE),
    bootstrap_results = function(self, init_state) {
      self$inner_kernel$bootstrap_results(init_state)
    },
    one_step = function(self, current_state, previous_kernel_results, seed = NULL) {
      seeds <- tf$unstack(tfp$random$split_seed(seed, n = 2L))
      n_leapfrog <- tf$random$stateless_uniform(
        shape = list(),
        seed = seeds[[1]],
        minval = self$l_min,
        maxval = self$l_max + 1L,
        dtype = tf$int32
      )
      accepted <- previous_kernel_results$accepted_results$`_replace`(
        num_leapfrog_steps = n_leapfrog
      )
      results <- previous_kernel_results$`_replace`(accepted_results = accepted)
      self$inner_kernel$one_step(current_state, results, seed = seeds[[2]])
    }
  )
)

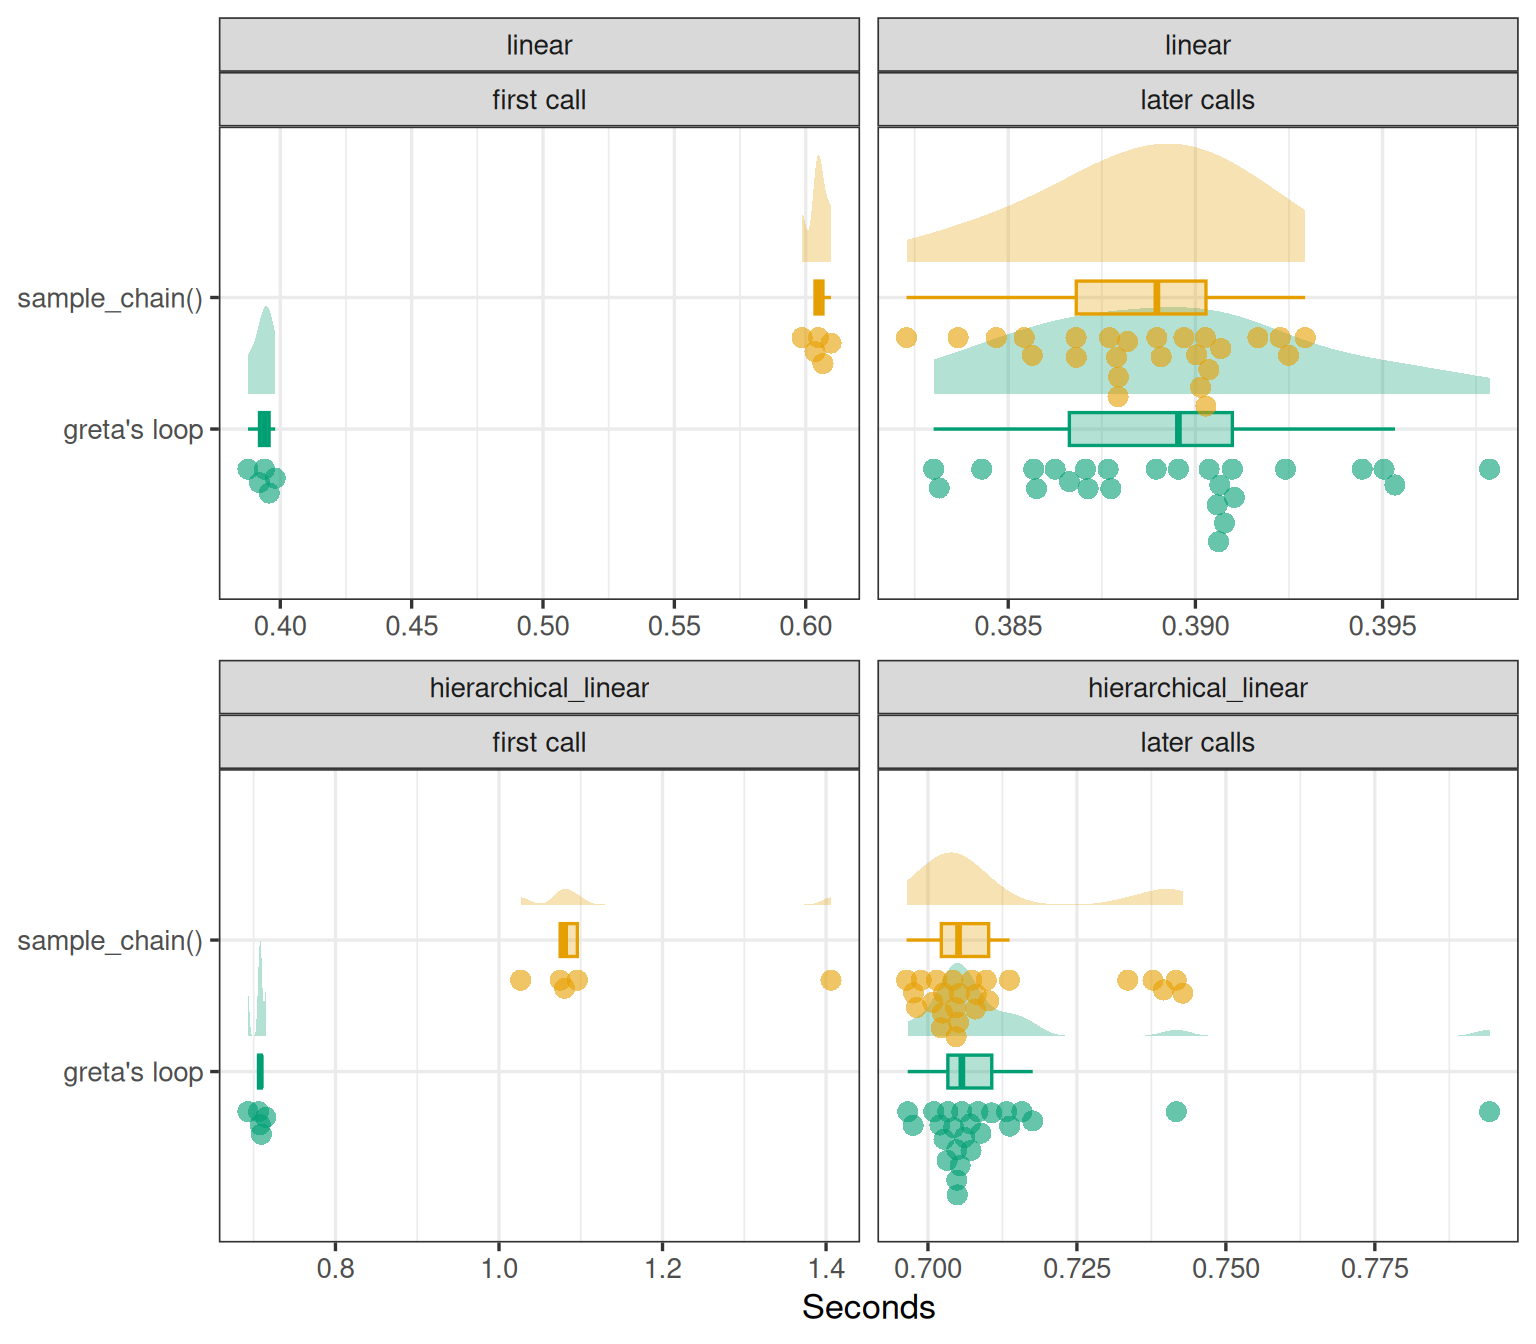
# ---- benchmark-sampling ----
# A model's sampler, tuned by one mcmc() call, then run for
# sampling_iterations two ways from the same state, step sizes and leapfrog
# range: through greta's own traced loop, called as mcmc() calls it, and
# through tfp$mcmc$sample_chain() with the wrapper kernel. Each is traced on
# its first call and reuses the trace after, so every call is kept and the
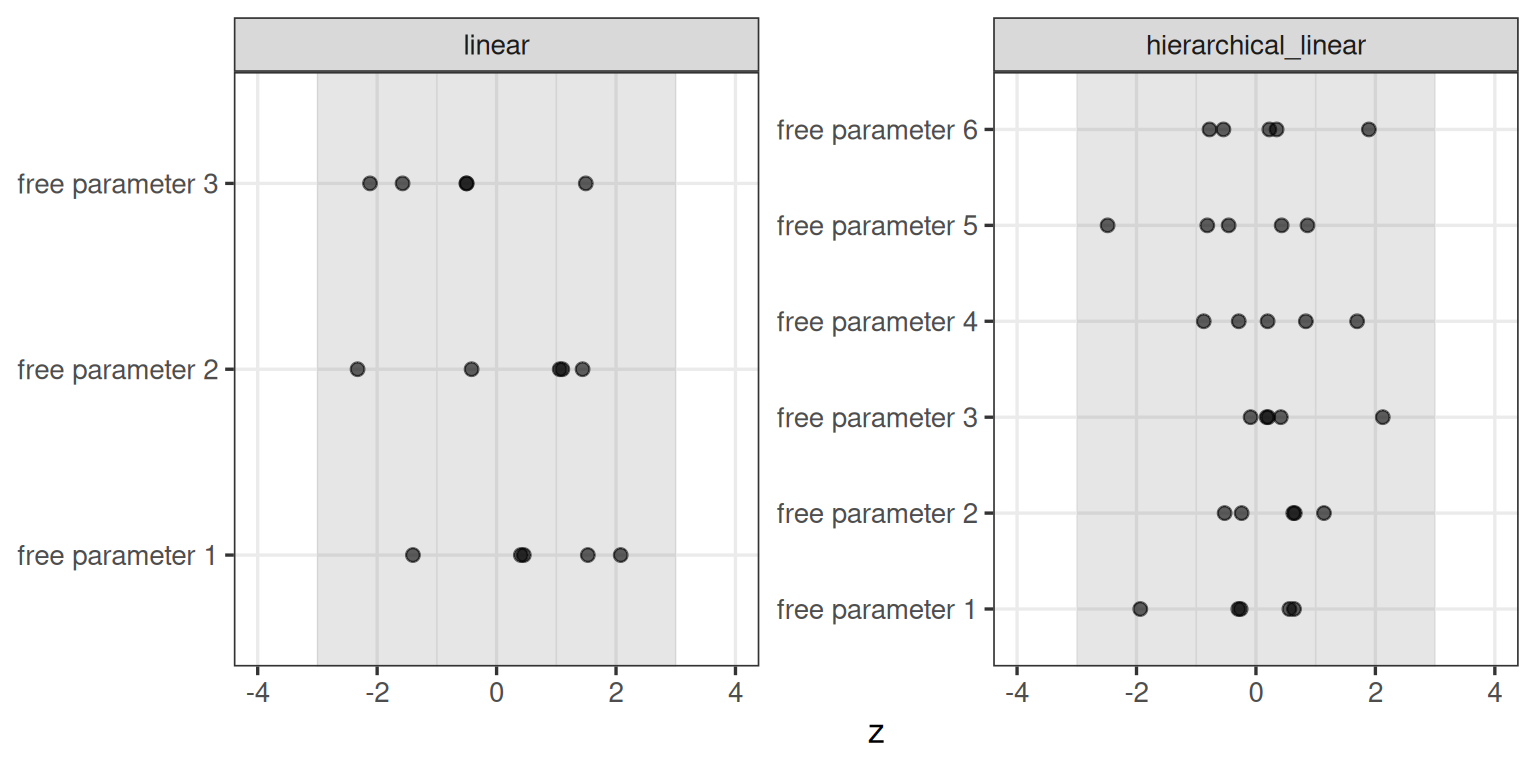
# post separates the first. Each also returns its draws, for the posterior
# means to compare.
bench_sampling <- function(m) {
  set.seed(session_seed)
  tuned <- mcmc(
    m,
    warmup = bench_settings$warmup,
    n_samples = 10,
    chains = bench_settings$chains,
    verbose = FALSE
  )
  sampler <- attr(tuned, "model_info")$samplers[[1]]
  dag <- m$dag
  float <- greta:::tf_float()
  n_free <- sampler$n_free
  param_vec <- unlist(sampler$sampler_parameter_values())
  diag_sd <- param_vec[3 + seq_len(n_free)]
  step_sizes <- param_vec[3] * diag_sd / sum(diag_sd)
  initial <- tensorflow::as_tensor(sampler$free_state, dtype = float)
  n <- bench_settings$sampling_iterations

  greta_loop <- function() {
    sampler$tf_iterations(
      free_state = initial,
      n_iterations = tensorflow::as_tensor(n),
      first_iteration = tensorflow::as_tensor(10000L),
      warmup = tensorflow::as_tensor(0L),
      sampling_start = tensorflow::as_tensor(10000L),
      thin = tensorflow::as_tensor(1L),
      param_vec = tensorflow::as_tensor(
        param_vec,
        dtype = float,
        shape = length(param_vec)
      ),
      tuning = tensorflow::as_tensor(rep(0, 6), dtype = float),
      welford_mean = tensorflow::as_tensor(rep(0, n_free), dtype = float, shape = n_free),
      welford_m2 = tensorflow::as_tensor(rep(0, n_free), dtype = float, shape = n_free),
      seed = tensorflow::as_tensor(c(session_seed, 0L), dtype = tf$int32)
    )$draws
  }

  tfp_chain <- tensorflow::tf_function(
    function(state) {
      inner <- tfp$mcmc$HamiltonianMonteCarlo(
        target_log_prob_fn = dag$tf_log_prob_function_adjusted,
        step_size = tf$constant(step_sizes, dtype = tf$float64),
        num_leapfrog_steps = as.integer(param_vec[1]),
        store_parameters_in_results = TRUE
      )
      kernel <- RandomLeapfrog(
        inner,
        l_min = as.integer(param_vec[1]),
        l_max = as.integer(param_vec[2])
      )
      tfp$mcmc$sample_chain(
        num_results = n,
        current_state = state,
        kernel = kernel,
        trace_fn = function(current_state, kernel_results) {
          kernel_results$log_accept_ratio
        },
        seed = as.integer(c(session_seed, 1L))
      )$all_states
    },
    input_signature = list(tf$TensorSpec(
      shape = list(as.integer(bench_settings$chains), n_free),
      dtype = float
    ))
  )
  tfp_loop <- function() tfp_chain(initial)

  draws <- list(greta = NULL, tfp = NULL)
  marks <- mark(
    greta = draws$greta <- as.array(greta_loop()),
    tfp = draws$tfp <- as.array(tfp_loop()),
    iterations = bench_settings$sampling_calls,
    check = FALSE,
    memory = FALSE,
    filter_gc = FALSE
  )
  list(marks = marks, draws = draws)
}

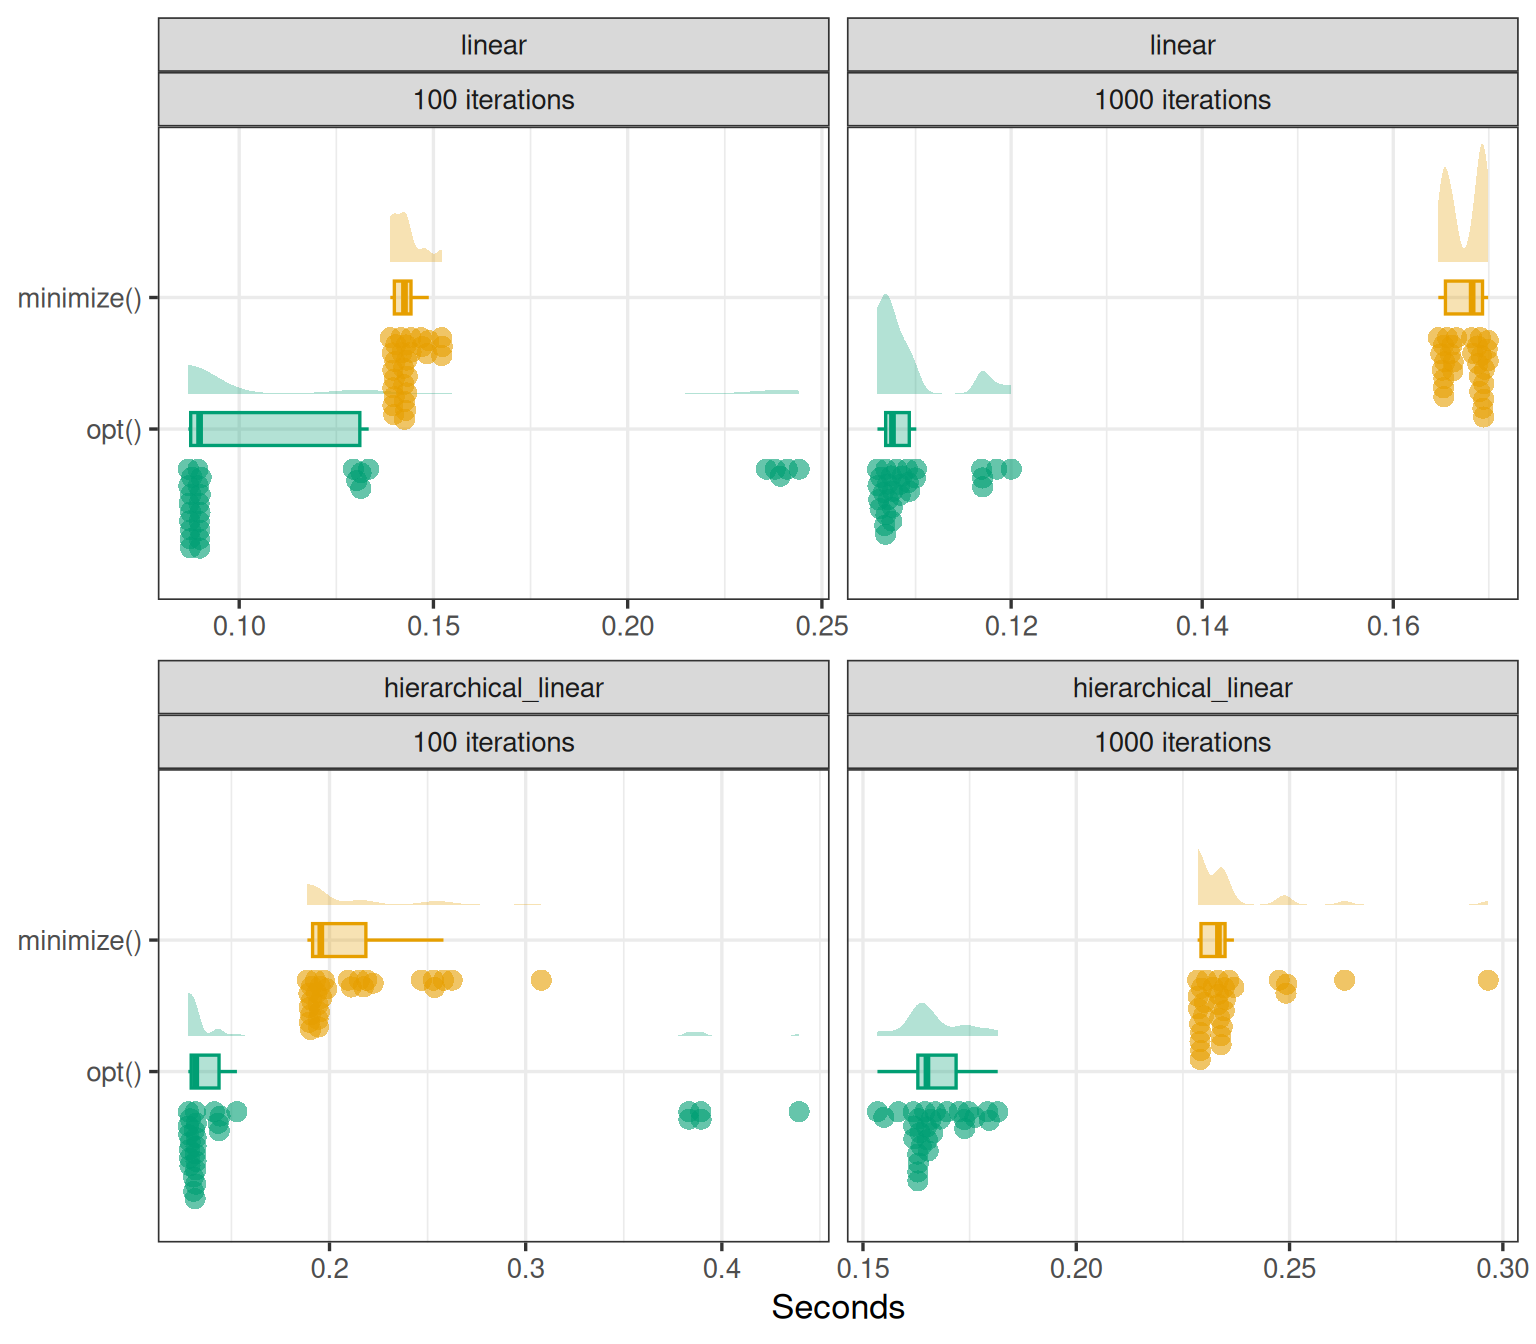
# ---- benchmark-opt ----
# opt() with adam(), against tfp$math$minimize() running the same Keras
# optimiser with greta's convergence rule: stop once successive objectives
# differ by at most the tolerance. That rule is a ConvergenceCriterion
# subclass written in R. opt() starts from small random values on the free
# scale, as it does by default, and minimize() from zero. Both build and trace
# their loop afresh on every call, as opt() does.
AbsoluteChange <- reticulate::PyClass(
  "AbsoluteChange",
  inherit = tfp$optimizer$convergence_criteria$ConvergenceCriterion,
  defs = list(
    `__init__` = function(self, tolerance) {
      tfp$optimizer$convergence_criteria$ConvergenceCriterion$`__init__`(
        self,
        min_num_steps = 1L,
        name = "AbsoluteChange"
      )
      self$tolerance <- tolerance
      NULL
    },
    `_bootstrap` = function(self, loss, grads, parameters) {
      loss
    },
    `_one_step` = function(self, step, loss, grads, parameters, auxiliary_state) {
      reticulate::tuple(
        tf$less_equal(tf$abs(loss - auxiliary_state), self$tolerance),
        loss
      )
    }
  )
)

opt_tfp <- function(m, max_iterations, tolerance) {
  dag <- m$dag
  float <- greta:::tf_float()
  n_free <- length(greta:::unlist_tf(dag$example_parameters(free = TRUE)))
  free_state <- tf$Variable(matrix(0, 1, n_free), dtype = float)
  optimiser <- tf$keras$optimizers$Adam(
    learning_rate = bench_settings$opt_learning_rate
  )
  optimiser$build(list(free_state))
  # minimize() calls the loss with a seed, and falls back to calling it
  # without one only on Python's TypeError, which an R error is not
  loss <- function(seed = NULL) {
    tf$reshape(-dag$one_row_log_prob(free_state)$adjusted, shape = list())
  }
  run <- tensorflow::tf_function(function() {
    tfp$math$minimize(
      loss_fn = loss,
      num_steps = max_iterations,
      optimizer = optimiser,
      convergence_criterion = AbsoluteChange(tolerance = tolerance),
      trainable_variables = list(free_state)
    )
  })
  run()
  free_state$numpy()
}

bench_opt <- function(m) {
  bench::press(
    max_iterations = bench_settings$opt_max_iterations,
    {
      set.seed(session_seed)
      mark(
        greta = opt(
          m,
          optimiser = adam(learning_rate = bench_settings$opt_learning_rate),
          max_iterations = max_iterations,
          tolerance = 0
        ),
        tfp = opt_tfp(m, max_iterations, tolerance = 0),
        iterations = bench_settings$opt_calls,
        check = FALSE,
        memory = FALSE,
        filter_gc = FALSE
      )
    }
  )
}

# ---- bench-linear ----
linear_model <- build_linear()
linear_sampling <- bench_sampling(linear_model)
linear_opt <- bench_opt(linear_model)

# ---- bench-hierarchical-linear ----
hierarchical_linear_model <- build_hierarchical_linear()
hierarchical_linear_sampling <- bench_sampling(hierarchical_linear_model)
hierarchical_linear_opt <- bench_opt(hierarchical_linear_model)

# ---- benchmark-provenance ----
session_info <- sessioninfo::session_info()
# greta_sitrep() reports through messages, so capture those
greta_sitrep_report <- utils::capture.output(greta_sitrep(), type = "message")

provenance <- data.frame(
  greta_version = as.character(packageVersion("greta")),
  r_version = paste(R.version$major, R.version$minor, sep = "."),
  tensorflow_version = tf$version$VERSION,
  tfp_version = tfp$`__version__`,
  reticulate_version = as.character(packageVersion("reticulate")),
  machine = paste(
    Sys.info()[c("sysname", "release", "machine")],
    collapse = " "
  ),
  cores = parallel::detectCores()
)

# ---- benchmark-results ----
# the value source() returns to run.R: every bench_mark object as mark() and
# press() made it, with each sampling run's draws beside it
list(
  session_seed = session_seed,
  bench_settings = bench_settings,
  provenance = provenance,
  session_info = session_info,
  greta_sitrep_report = greta_sitrep_report,
  sampling = list(
    linear = linear_sampling,
    hierarchical_linear = hierarchical_linear_sampling
  ),
  opt = list(
    linear = linear_opt,
    hierarchical_linear = hierarchical_linear_opt
  )
)